
A recent infographic on Azure Functions I saw on LinkedIn last week raised my interest. React uploads a document, Blob Storage stores it, a blob-triggered function processes it, SQL holds the metadata. Four boxes, four arrows, and a closing line I agree with: your API handles the request, Azure Functions can handle the work that happens afterward.
I have no quarrel with the picture. It is the right shape for a construction document portal, an insurance claims intake, or any upload that should not hold the HTTP request hostage. My quarrel is with the three sentences in the “best practice” box. Make processing idempotent. Handle retries and failures properly. Monitor with Application Insights. Each is correct, and each hides a design decision the diagram does not show. I built the pipeline to find out what those decisions cost.
The repo is at github.com/steefjan1/after-the-upload-azure. One azd up deploys it to your subscription.
First, the code box has a date on it
Look at the code sample in the infographic. [FunctionName("ProcessDocument")], a Stream parameter and an ILogger log injected into the method. That is the in-process model. Microsoft ends support for the in-process model on November 10, 2026. As I write this, that is nineteen days away. The same day, .NET 8 itself leaves support.
That is not pedantry. The isolated worker model changes how the trigger is declared, how the host is configured and which packages you reference. If you copy the infographic’s snippet into a new project today, you are starting on a model that is about to be unsupported. Every line of code in this post is isolated worker, .NET 8, and the csproj has a comment on how to move it to .NET 10.
Three things the arrow from Blob Trigger to SQL does not show

Flex Consumption, the blob trigger is an Event Grid trigger in disguise
One: on Flex Consumption, the blob trigger is an Event Grid trigger in disguise. The classic blob trigger scans container logs and polls. It is slow to fire, it misses blobs on busy accounts, and Flex Consumption does not support it at all. The plan only runs the event-based variant: Source = BlobTriggerSource.EventGrid on the attribute, plus an Event Grid subscription on the storage account that calls a webhook on the function host. That subscription is a separate resource with its own retry schedule, its own dead-letter location and a system key in its URL that only exists after the code has been deployed once. My Bicep creates the system topic; a post-deploy script creates the subscription. The portal tutorial has you click through it. Either way it is not “add the attribute and go”.


Retries are not where you think, and I had it wrong before I ran it
Two: retries are not where you think, and I had it wrong before I ran it. The runtime retry policies, FixedDelayRetry and ExponentialBackoffRetry, cover four trigger types: Cosmos DB, Event Hubs, Kafka and Timer. Blob is not one of them. My draft then said the retry is Event Grid redelivering after a non-2xx, on Event Grid’s schedule of 10 seconds, 30 seconds, 1 minute and up. The first run disproved that in six seconds.
The blobs webhook answers 202 Accepted before your code runs: the extension drops the event on an internal queue in the function’s storage account and returns. That is why the trigger needs Storage__queueServiceUri and a Queue Data Contributor role even though you never declared a queue. Event Grid is done the moment the host has queued the event.
The retries you get when the function throws are the host’s queue listener redelivering the message, immediately, up to maxDequeueCount (5 by default), after which the message goes to webjobs-blobtrigger-poison. Event Grid’s own retry schedule and the dead-letter container only come into play when the webhook itself fails: host down, wrong key, or the quoting bug I describe below. Your function sees none of this either way. It sees the same blob, again, and faster than you expect.
At-least-once delivery means the function has to count
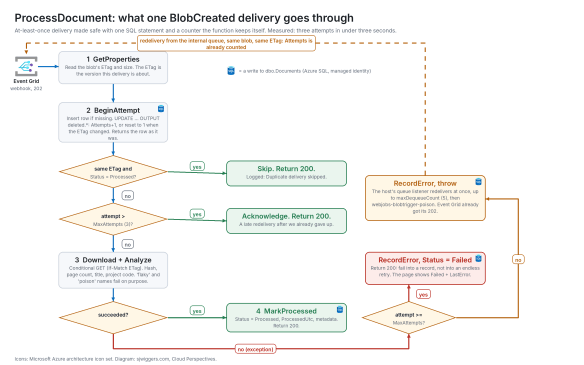
Three: at-least-once delivery means the function has to count. “Make it idempotent” is the correct instruction and the diagram gives you nothing to be idempotent with. The question is what the key is. I use the blob name plus its ETag. The same name with a new ETag is a new upload and starts over. The same name with the same ETag and a row that already says Processed is a duplicate delivery, and the function returns 200 without touching the blob. Everything in between is an attempt the function numbers itself, because Event Grid does not tell you which delivery this is.
The attempt gate
SQL Statement
The gate is one SQL statement. OUTPUT deleted.* returns the row as it was before the update, so the function learns what the previous delivery left behind in the same round trip that records this one.
UPDATE dbo.DocumentsSET Attempts = CASE WHEN ETag IS NOT NULL AND ETag <> @ETag THEN 1 ELSE Attempts + 1 END, Status = CASE WHEN ETag IS NOT NULL AND ETag <> @ETag THEN @Processing WHEN Status = @Processed THEN Status ELSE @Processing END, ProcessedUtc = CASE WHEN ETag IS NOT NULL AND ETag <> @ETag THEN NULL ELSE ProcessedUtc END, ETag = @ETag, UpdatedUtc = SYSUTCDATETIME()OUTPUT deleted.*WHERE BlobName = @BlobName;
The Function
The function then has four exits, and which one it takes decides what the host does next:
var before = await _repo.BeginAttemptAsync(name, fileName, etag, ct);var sameVersion = before.ETag == etag;if (sameVersion && before.Status == DocumentStatus.Processed) return; // duplicate: 200, nothing to redovar attempt = sameVersion ? before.Attempts + 1 : 1;if (attempt > _options.MaxAttempts) return; // late redelivery after we gave up: 200try{ var meta = _analyzer.Analyze(fileName, props.ContentType, bytes, attempt); await _repo.MarkProcessedAsync(name, etag, meta, ct);}catch (Exception ex) when (ex is not OperationCanceledException){ var final = attempt >= _options.MaxAttempts; await _repo.RecordErrorAsync(name, ex.Message, final, ct); if (final) return; // fail into a record: 200, Status = Failed throw; // the host's queue listener redelivers, right away}
Returning on the final failure is the decision I want to draw attention to. Throwing forever is easy and it is what most samples do. The message then burns through its dequeue count, lands in a poison queue nobody reads, and the user’s document says Pending until the end of time. Writing Failed and LastError into the row and returning normally puts the failure where the status endpoint can show it. The poison queue and the Event Grid dead-letter container are still there, but they are safety nets for the host misbehaving, not the normal path for a document that cannot be parsed.
The fourth box the infographic needed
The user. The React page in the infographic uploads and the story ends. In mine it asks the API for a ten-minute user delegation SAS, PUTs the file into Blob Storage itself, and then polls GET /api/documents/{id} until the status is Processed, Failed or Stalled.
Stalled is the one that took a timer trigger to produce. A SAS gets issued and the browser closes. An event subscription filter does not match. The row sits at Pending and nothing in the retry or dead-letter machinery will ever notice, because no event was ever delivered. SweepStalePending runs every five minutes and marks any row Pending for more than ten minutes as Stalled. It is the smallest function in the repo and the only one that catches that failure.

What the runs show
Three files in samples/ exercise the paths; scripts/demo.ps1 uploads one and polls the status endpoint every three seconds.
PRJ-2041-site-plan.pdf processed on the first delivery: three pages, project code PRJ-2041 pulled from the first page by PdfPig, SHA-256 in the row, 320 ms from the row being created to ProcessedUtc.

flaky-PRJ-2041-rfi.pdf throws on attempts one and two and succeeds on three. The traces put the three attempts at 13:30:34.518, 13:30:35.091 and 13:30:35.194 UTC: gaps of 573 and 103 milliseconds, two exceptions and two redeliveries inside 676 milliseconds. That is the queue listener, not Event Grid, whose first retry would not have arrived for another nine seconds.


The poison drawing
poison-drawing.pdf throws every time. The first poll already showed Failed attempts=3 with the exception message in LastError. Nothing went to the poison queue and nothing went to the dead-letter container, because the third attempt returned normally. The requests table for that minute shows six invocations of ProcessDocument, four failed and two succeeded: flaky (fail, fail, succeed) and poison (fail, fail, and a third that succeeded as far as the host is concerned, because it wrote Failed and returned). The webhook calls themselves never appear in requests; only invocations do.


scripts/replay-event.ps1 posts the BlobCreated event for the already-processed site plan to the webhook twice more, exactly the payload Event Grid sends. Both deliveries came back 202, both were logged as “Duplicate delivery skipped”, and the row’s ProcessedUtc did not move. That is the idempotency claim, tested rather than asserted.

What the first run against Azure taught me
Two things that are not in any tutorial.
The subscription cannot be created from PowerShell on Windows the obvious way. az is az.cmd, so its arguments pass through cmd.exe, and cmd treats the & in the webhook URL as a command separator. Everything after it, starting with code=<key>, runs as a second command. On a machine with VS Code installed that opens an editor window with a file named after your function key, and the remaining flags become Electron warnings. Meanwhile az receives the URL without the key and Event Grid’s validation gets a 401. Wrap the URL in its own quotes before handing it to az; the script does.
And az eventgrid system-topic event-subscription create has no --deadletter-identity flags in the current CLI. The generic az eventgrid event-subscription create --source-resource-id <storage account> does, and it attaches to the system topic that already exists for that account.
Where this is the wrong answer
If one event must fan out to several independent steps with different retry needs, a queue per step or Durable Functions beats one blob trigger with a counter. Moreover, if ordering matters across documents, none of this helps; Event Grid does not order and the gate is per blob. ANd finally, if processing takes longer than the Flex Consumption timeout, or needs more than the memory you gave the instance, you are in Container Apps territory and the blob trigger is only the front door. And if you cannot give the function a managed identity on both Storage and SQL, stop and fix that first. Every connection in this repo is identity-based; the connection string with a key that the infographic’s Connection = "StorageConnection" implies is the part I would not ship.
Takeaways
The infographic is a good plan and a bad specification. On Flex Consumption the blob trigger is an Event Grid subscription you have to create and tune, feeding a queue you did not know you had. Retries come from that queue, fast, not from Event Grid and not from the function. Idempotency needs a key, and name plus ETag is a good one. Failure needs a place to land that the user can see. And the code sample has nineteen days of support left, so start on the isolated worker.
Code, Bicep, diagrams and the PowerShell scripts are in the repo. Run it, break it with a file called poison, and watch where the failure goes.

Sources:


